AnonVision
I built a privacy-first computer vision system that protects identity in sensitive visual media even when recognition fails.
AnonVision is a deterministic, offline face anonymization system for journalism, legal review, research, and surveillance workflows where a missed face can create real-world harm. Instead of treating privacy as a binary blur-everything problem, it gives users controlled selective visibility while preserving fail-safe protection by default.
The core design decision is architectural: protected individuals are explicitly whitelisted, while everyone else is anonymized automatically. That means the system fails closed. If recognition fails, privacy is preserved instead of exposed.
Product Snapshot
- • Problem: Identity exposure in sensitive photos and evidence workflows
- • Solution: Deterministic offline face anonymization pipeline
- • Key Model: Whitelist visible subjects, anonymize everyone else
- • Constraint: CPU-only, offline, reproducible, audit-friendly
- • Detection: 99%+ frontal accuracy using YuNet on CPU
- • Risk Strategy: Recognition failure results in anonymization, not exposure
"I need to protect confidential sources in protest photos but keep the journalist visible."
- User Research Participant
Why Fail-Safe Design Is Non-Negotiable Here
Facial imagery is increasingly treated as sensitive by design, not just by convention. The EU AI Act classifies real-time facial recognition as high-risk AI, and GDPR Article 9 treats facial imagery as special-category biometric data requiring explicit consent or a lawful basis. That's the design constraint the system had to satisfy from the start, not a compliance checkbox added afterward: any AI system that touches facial data needs an architecture where uncertainty defaults to protection.
Existing tools force an uncomfortable choice: cloud-based detection introduces a transfer risk that regulators are actively scrutinizing, while all-or-nothing blur tools ignore that anonymization is a judgment call, not a binary. Both are design failures before they are compliance failures. AnonVision's answer was to make that AI product design decision explicit - whitelist visible subjects, fail closed on everyone else, and never let a single frame leave the device.
Selective anonymization exists because privacy is not binary. In journalism, legal review, and research contexts, some people must remain visible while others must be protected. That turns anonymization into a control problem: how do you give humans granular authority over algorithmic identity decisions without creating unsafe defaults?
Offline CPU inference is not a performance compromise. It is a trust boundary. No network egress means no data exfiltration vector. Deterministic execution means audit-ready reproducibility. This system was designed for contexts where the cost of a false negative is measured in human safety, legal exposure, or compliance failure.
- Role Visual Systems Designer & ML Engineer
- Timeline Sep 2025 – Present
- Tech Stack Python, OpenCV, YuNet DNN, ONNX Runtime, Tkinter
- Constraints CPU-only, Offline, Deterministic
- Primary Decision Fail-safe whitelist architecture
- Deployment Model Local-only processing with no external API dependency
- GitHub View Repository →
The hard calls, and how I made them
Privacy isn't a feature you layer on later, it's a failure model. The real design question was never whether the system works under ideal conditions, but what it does when it fails.
The intuitive UI metaphor was the unsafe one. A blacklist model, select the faces to hide, fails unsafe, because a recognition failure leaves someone exposed in the exported file.
How I solved itI inverted it to a whitelist: every face is anonymised by default and only explicitly confirmed faces are revealed. A recognition failure now still protects the person.
Principle: Follow the safer failure mode, not the more intuitive metaphor.Cloud would have demoed better. Cloud APIs are easier to build and show off, but sending sensitive footage to a third party is unacceptable for journalists, legal review and research workflows.
How I solved itFully offline local execution, removing transfer risk, vendor dependence, and preserving data sovereignty in the workflows that need it most.
Principle: The trust model sets the architecture, not the other way round.Peak throughput wasn't the goal. Faster inference is the obvious optimisation, but non-deterministic output can't be defended in an audit or reproduced for legal review.
How I solved itDeterministic CPU inference, chosen so the same input always yields the same output and the system holds up under scrutiny.
Principle: Repeatability matters more than speed in evidentiary contexts.One-click AI would have hidden the risk. Automation that quietly makes decisions is exactly what a privacy-critical user can't afford to trust.
How I solved itThe interface keeps every important decision visible: users inspect detections, confirm protected faces, and verify output before export.
Principle: Legibility over automation theatre.Design principles & psychology at work
The design stance behind the build:
- Fail safe, not fail quietEvery default resolves toward protection when the system is uncertain.
- Privacy as a failure modelDesigned around what happens when detection misses, not when it succeeds.
- Human-controlled decisionsAI accelerated research synthesis and implementation; the product and safety decisions stayed explicitly human.
- Defensibility as a requirementDeterminism and local processing were chosen so the tool survives audit and legal review.
01Overview
AnonVision solves a systems architecture problem: how do you build a face anonymization pipeline that is deterministic, auditable, and fail-safe without relying on cloud infrastructure, GPU hardware, or network connectivity?
99%+
Detection Accuracy (Frontal)
CPU
Deterministic Inference
0
Network Dependencies
100%
Replay Reproducibility
Why This System Is Different
- • Most anonymization tools fail open - a missed face remains exposed
- • AnonVision fails closed -detection uncertainty still preserves privacy by default
- • Cloud pipelines create transfer and exfiltration risk - this runs fully offline
- • GPU-heavy stacks can complicate reproducibility - this is deterministic on CPU
- • Manual editing does not scale - this enforces consistent privacy behavior automatically
Architectural Guarantees
Deterministic Pipeline: The same input image produces identical output across runs. That matters for legal reproducibility, forensic review, and audit trails.
Trust Boundary Enforcement: All processing occurs locally. No image data crosses network boundaries. No external API dependencies exist after install.
Fail-Safe Defaults: The system defaults to maximum anonymization. Protection requires explicit user action. Recognition failure results in anonymization, not exposure.
Audit-Friendly Output: The original image remains preserved until explicit save. Transformations are reversible during session, and the output contains no hidden behavior or metadata surprises.
It is not a speculative concept. It is designed for deployment in air-gapped or tightly controlled environments where predictability matters more than flashy model demos.
02Application Snapshot
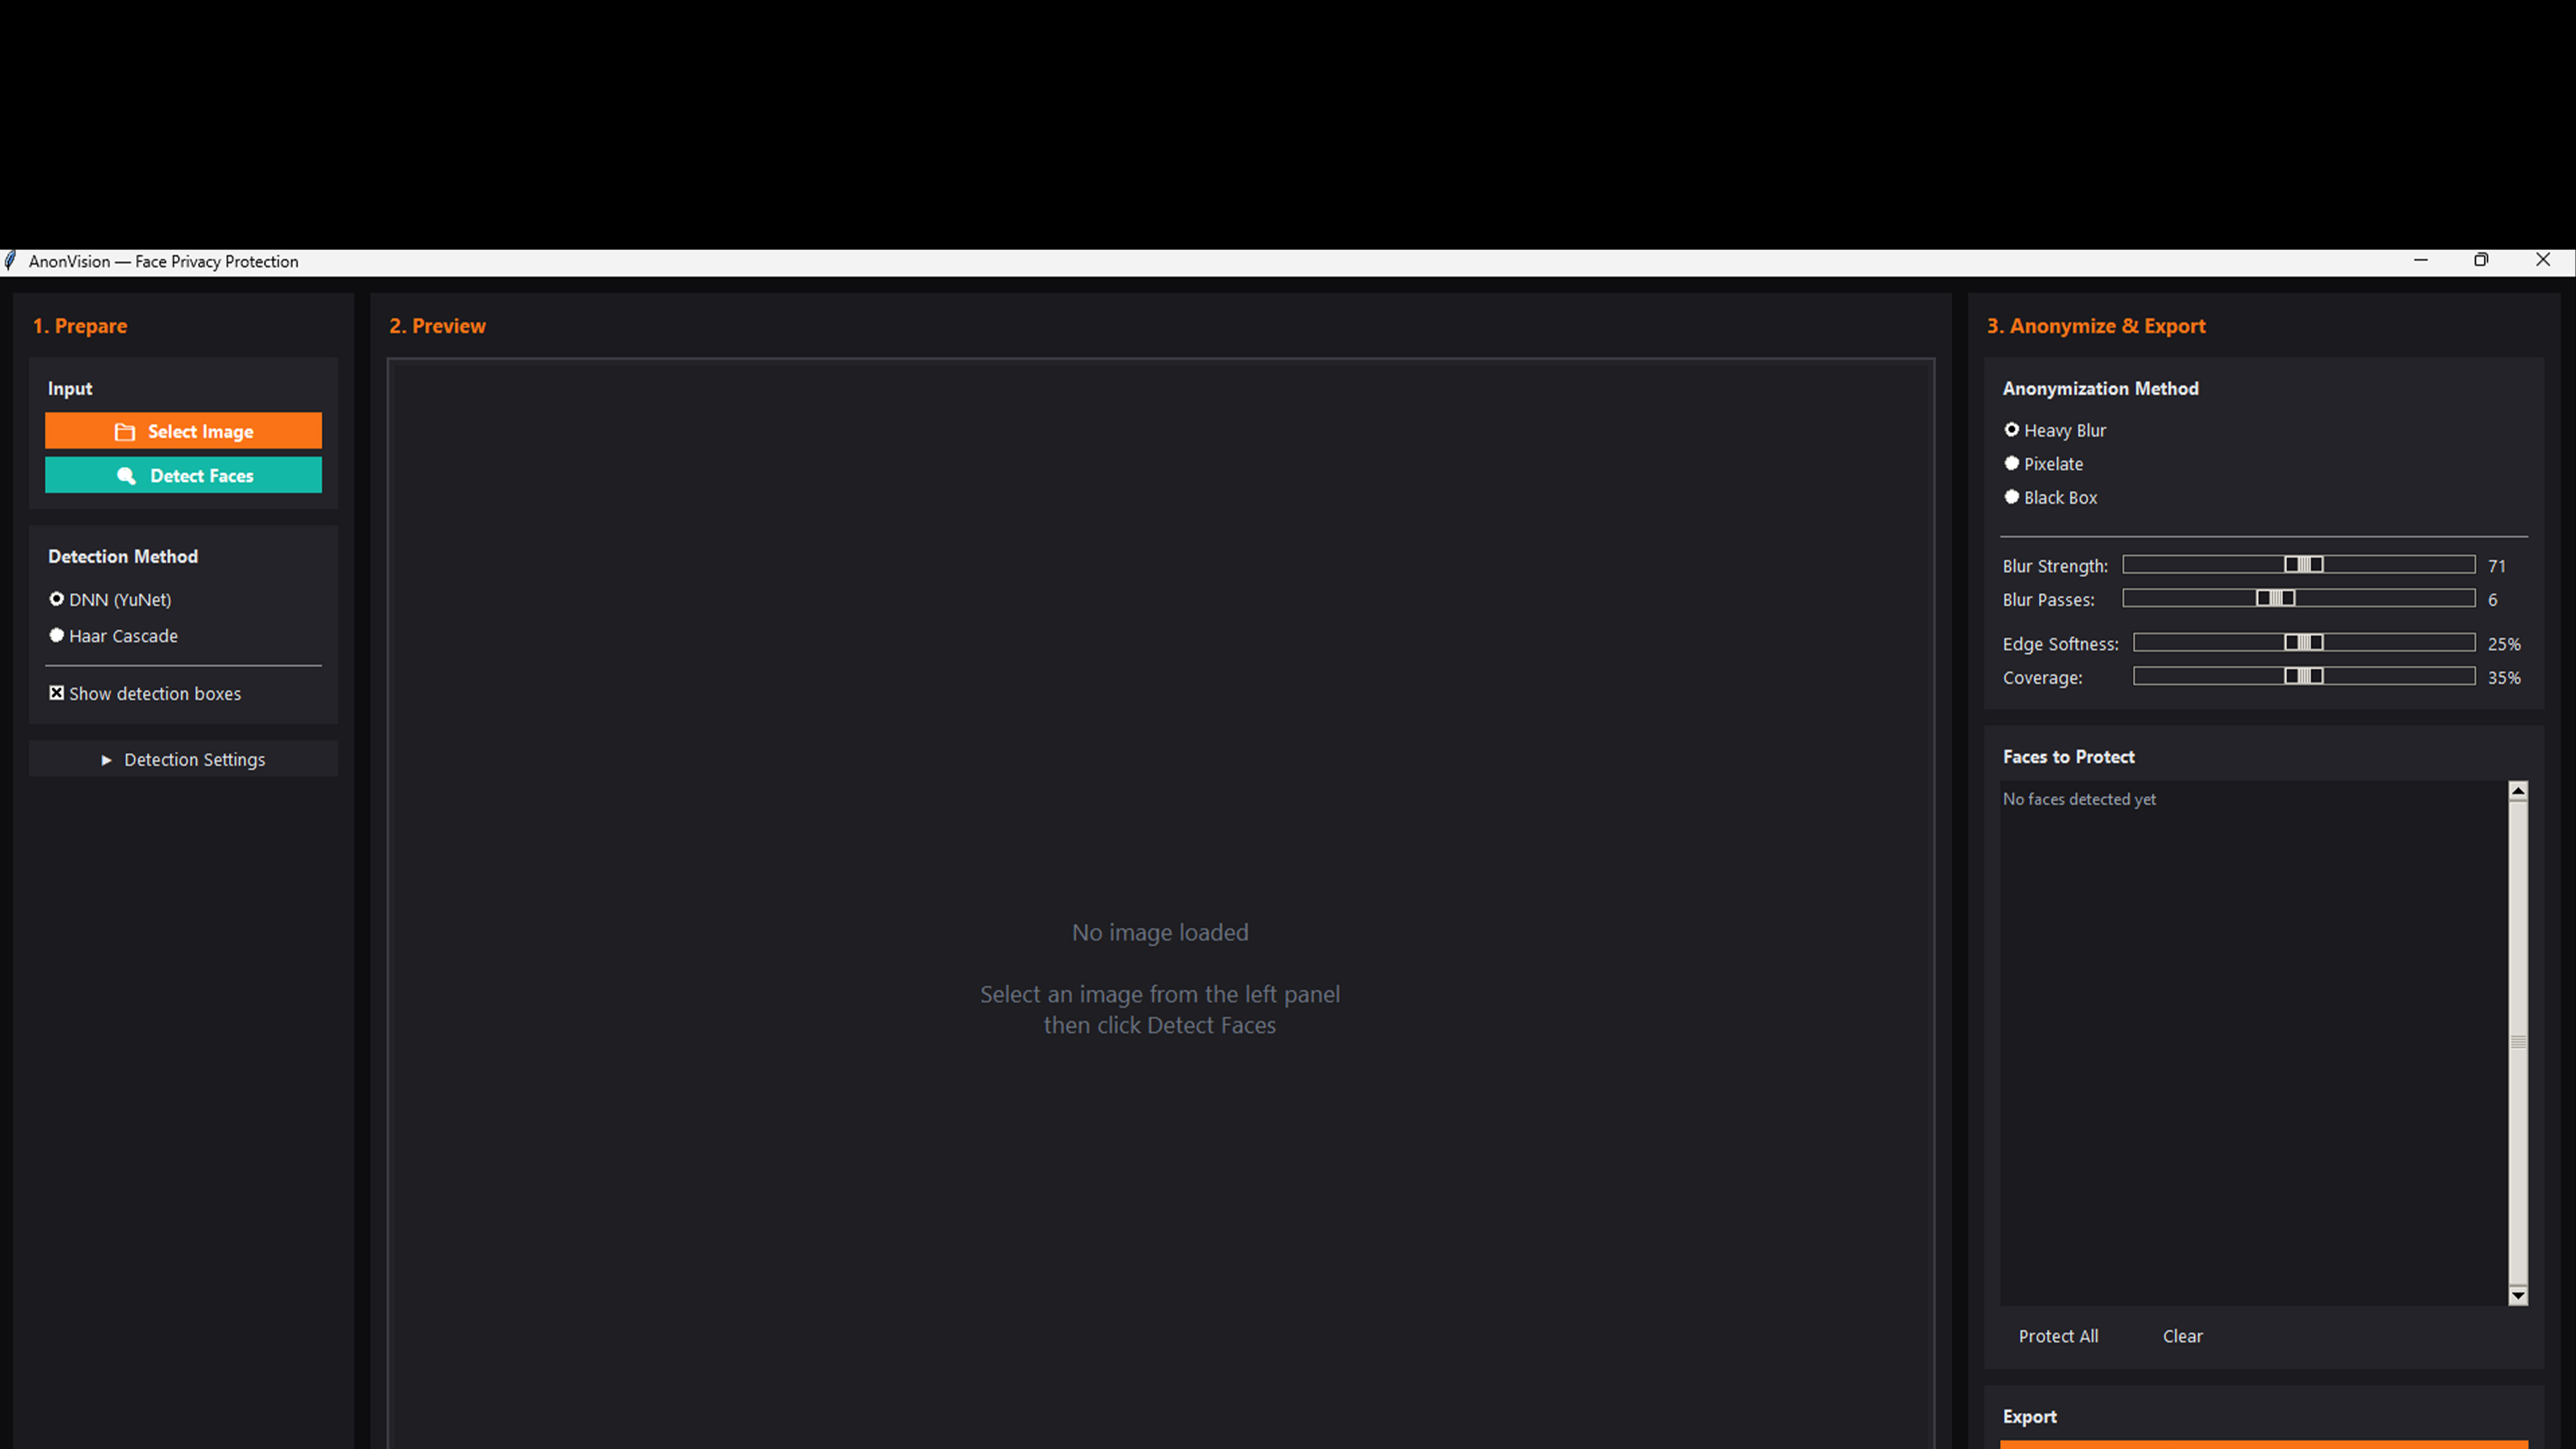
The interface keeps every privacy decision legible. Users can inspect detections, assign protection explicitly, apply anonymization from the original source image, and verify the result before export.
03System Demonstration
This walkthrough covers the full workflow: image ingestion, face detection, protection assignment, anonymization application, and output verification.
04Problem Landscape
Face anonymization is not a convenience feature. In regulated and safety-critical contexts, it is a compliance requirement with legal and human consequences for failure.
These users cannot afford false negatives or ambiguous failure modes. A missed face in a protest photo can lead to retaliation. A visible bystander in research footage can violate IRB protocol. An identifiable plaintiff in legal discovery can create liability exposure.
Journalistic Source Protection
Reporters documenting protests, conflict zones, or sensitive investigations need to publish visual evidence while protecting confidential sources from identification and retaliation.
Constraint: Selective visibility. The journalist may remain visible while sources must be anonymized.
IRB Protocol Compliance
Institutional Review Boards increasingly require face anonymization in published research imagery. Manual pixel editing introduces human error and does not scale.
Constraint: The process must be reproducible, auditable, and methodologically defensible.
GDPR & Privacy Regulation
Biometric processing under GDPR Article 9 requires explicit consent or another lawful basis. Facial imagery in public datasets, surveillance review, or media assets creates compliance exposure.
Constraint: Demonstrable anonymization with strong data sovereignty and minimized transfer risk.
Legal Discovery & Surveillance Review
Organizations reviewing security footage or discovery materials need to protect uninvolved parties while preserving evidentiary value for relevant subjects.
Constraint: Chain-of-custody integrity and consistent output that can survive scrutiny.
Common Requirement
Across all four domains, the same architectural requirements appear: deterministic output for reproducibility, offline execution for data sovereignty, selective control for nuanced privacy decisions, and fail-safe behavior where system errors preserve privacy rather than compromise it.
05Research & Discovery
Detector selection was not a benchmark vanity exercise. It was a risk-reduction process. Each candidate detector was evaluated against privacy-grade requirements where a missed face means identity exposure.
Who I Designed For
I conducted discovery interviews and secondary research across four user archetypes, documentary journalists, IRB research coordinators, legal discovery analysts, and open-source dataset maintainers. Three patterns appeared consistently across all four groups:
"I can't upload source photos to any cloud tool, my newsroom policy forbids it."
- Documentary journalist, conflict reporting
"Our IRB requires reproducible redaction, we need to prove we ran the same process every time."
- Research coordinator, behavioral study
"Blur-everything tools are useless for us, the subject has to be identifiable, only bystanders get redacted."
- Legal discovery analyst, civil litigation
These three constraints, no cloud transfer, reproducible output, selective control, directly drove every major architectural decision in AnonVision.
Detector Evaluation: Failure Mode Analysis
Why YuNet Met Privacy-Grade Requirements
Deterministic Execution: ONNX Runtime on CPU produces stable output across runs, which is essential for legal reproducibility and audit trails.
Single-File Deployment: One .onnx model file, minimal runtime surface, and no dependency on external services after installation.
Bounded Failure Envelope: Known edge cases are preferable to unpredictable degradation because they can be communicated and mitigated.
Graceful Degradation: Haar Cascade fallback preserves functionality if ONNX Runtime fails, reducing the chance of silent detector collapse.
06Technical Architecture
The architecture is not just a delivery mechanism. It is the privacy enforcement model. Every major design choice exists to optimize predictability, legibility, and fail-safe behavior.
System Model
Input Layer: Local image ingestion through a desktop interface with no remote upload path.
Detection Layer: YuNet ONNX inference running on CPU with explicit validation and fallback behavior.
Decision Layer: User-controlled protection assignment determines visibility boundaries.
Transformation Layer: Anonymization always starts from the original image state, preventing cumulative corruption.
Output Layer: User-verified export with no network transmission and no hidden processing branch.
Trust Boundary: The system remains local-only from ingest to export.
Detection Pipeline
Sequential processing with explicit validation at each stage. No hidden transformations.
Anonymization Pipeline
Idempotent operations. Every apply step starts from the original image rather than stacking transformations on already modified output.
07Product Decisions That Mattered
Whitelist vs. Blacklist
This was the defining safety decision. A blacklist model fails unsafe because recognition failure leaves someone exposed. A whitelist model fails safe because recognition failure still anonymizes by default. The product direction followed the safer failure mode, not the more intuitive UI metaphor.
Offline Execution vs. Cloud Convenience
Cloud APIs would have been easier to demo, but unacceptable for the trust model. Offline local execution removes transfer risk, reduces vendor dependence, and preserves data sovereignty in sensitive workflows.
Determinism vs. Raw Throughput
In this problem space, repeatability matters more than peak throughput. Deterministic CPU inference made the system more defensible for audits, legal review, and reproducibility-sensitive contexts.
Legibility Over Automation Theater
The user interface was designed to keep every important decision visible. Users inspect detections, confirm protected faces, and verify output before export. That transparency matters more here than one-click AI magic.
08AI-Augmented Workflow
I used AI as a thinking and acceleration layer across research synthesis, system reasoning, and implementation planning, not as a substitute for architectural decisions. The key product and safety decisions remained explicitly human-controlled.
Research Synthesis
I used AI-assisted synthesis to cluster qualitative problem patterns around privacy risk, failure tolerance, and trust boundaries, which helped sharpen the architecture around fail-safe behavior.
Architecture Reasoning
I used AI tooling to stress-test tradeoffs around detector selection, failure modes, and privacy guarantees before committing to the YuNet + deterministic CPU approach.
Implementation Acceleration
AI-assisted coding helped compress iteration time during pipeline integration, fallback planning, and interface logic, while the final product behavior remained intentionally designed and validated.
09Reflections
AnonVision sharpened how I think about privacy systems: privacy is not a feature you layer on later. It is a failure model. The real design question is not whether a system works under ideal conditions. It is what the system does when it fails.
The most important decision in this project was not detector choice or UI polish. It was deciding that the product should fail closed. That one principle shaped everything from architecture and inference constraints to interaction design and output review.
This project also reinforced that trustworthy AI products do not come from model accuracy alone. They come from explicit boundaries, legible user control, predictable system behavior, and architectures that align technical failure with safer real-world outcomes.
I carry that mindset into every AI system I design now: choose the failure mode first, design the trust boundary deliberately, and make the product understandable enough that humans can defend it, not just use it.
Key Takeaway
The real product innovation was not blur quality. It was designing a privacy system where uncertainty defaults to protection, not exposure.